
Quick answer: A JavaScript array is an ordered list you access by index; an object is a set of key-value pairs you access by name. Arrays come with methods such as map, filter, reduce and find that transform data without manual loops. Objects hold related values together, and destructuring pulls the fields you need into local variables.The sections below cover JavaScript arrays and objects together: creating and reading them, the four transforming methods, copying and combining, then destructuring, which is what makes JavaScript arrays readable in modern code.
Table of Contents
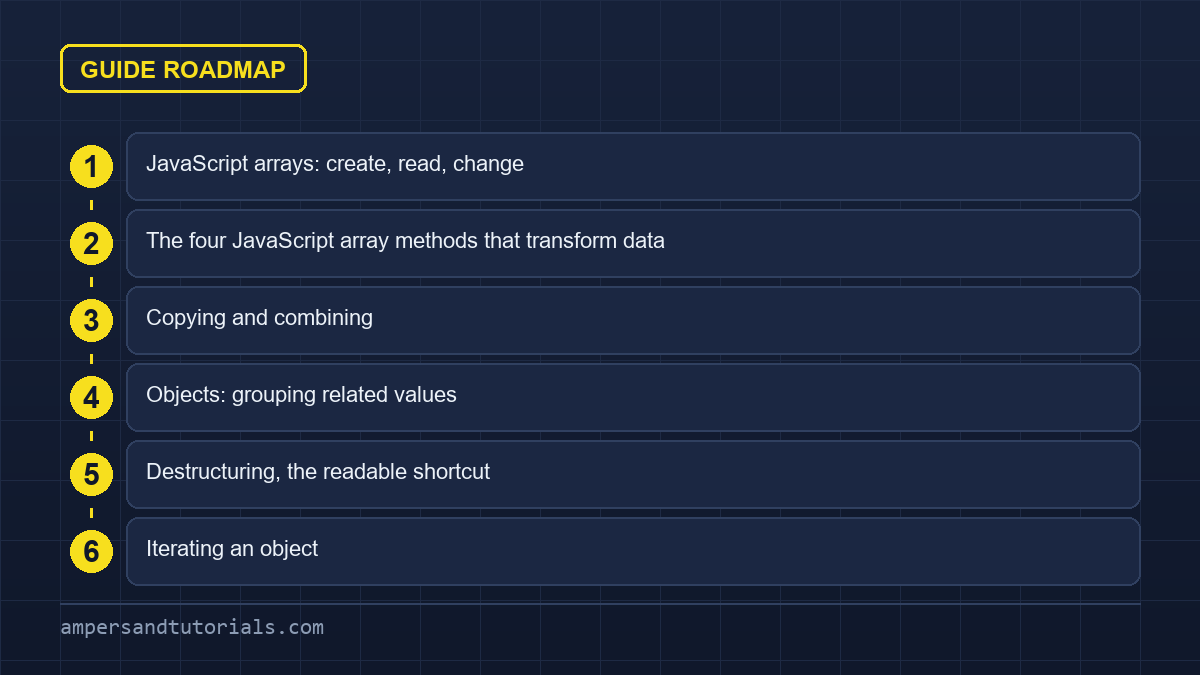
JavaScript arrays: create, read, change
const fruits = ["apple", "banana", "cherry"];

fruits[0];            // "apple"
fruits.length;        // 3
fruits.push("date");  // add to the end, returns new length
fruits.pop();         // remove from the end
fruits.includes("kiwi"); // false
Indexes start at zero, and arr[arr.length - 1] is the last item — though arr.at(-1) is the cleaner modern form.
The four JavaScript array methods that transform data
const prices = [10, 25, 4, 60];

prices.map(p => p * 1.2);           // [12, 30, 4.8, 72] — same length
prices.filter(p => p >= 20);        // [25, 60] — shorter
prices.reduce((sum, p) => sum + p, 0); // 99 — one value
prices.find(p => p > 50);           // 60 — first match
prices.some(p => p > 100);          // false
prices.every(p => p > 0); // truemap— transform each item, keep the length.filter— keep the items that pass a test.reduce— boil the list down to a single value.find— return the first match, orundefined.
All of these return a new array and leave the original untouched.
That immutability is why they compose so well: you can chain map after filter without worrying about what changed underneath.
Copying and combining
const copy = [...prices];              // shallow copy via spread
const merged = [...a, ...b];           // combine two arrays
const withoutOne = prices.toSpliced(1, 1);  // new array, item 1 removed
prices.toSorted((x, y) => x - y);      // sort without mutating
The methods ending in ed — toSorted, toSpliced, toReversed — are non-mutating versions of the older sort, splice and reverse, which all change the array in place. Prefer the non-mutating forms in modern code.

Objects: grouping related values
const user = {
  name: "Ada",
  role: "engineer",
  active: true,
  greet() { return `Hi, ${this.name}`; },
};

user.name;            // "Ada"
user["role"];         // "engineer" — bracket form for dynamic keys
user.email ??= "n/a"; // assign only if currently null/undefined
Objects can hold functions, which become methods. Dot notation is the readable default; the bracket form is for keys computed at runtime, such as user[fieldName].
Destructuring, the readable shortcut
const { name, role = "guest" } = user;      // pull out, with a default
const [first, second, ...rest] = fruits;    // from an array

const updated = { ...user, active: false }; // copy, then override one field
The spread form is how you update state immutably: copy the object, change one field, and you have a new reference. Every modern framework — including Angular — relies on this pattern for change detection.
Iterating an object
Object.keys(user);          // ["name", "role", ...]
Object.values(user);        // ["Ada", "engineer", ...]
Object.entries(user);       // [["name", "Ada"], ...]

for (const [key, value] of Object.entries(user)) {
  console.log(key, value);
}
Next: DOM manipulation. To learn JavaScript with a mentor on real projects, Ampersand Academy teaches web development one-to-one.

Sparse slots and empty elements in JavaScript arrays
Developers often assume indexed collections always hold contiguous items, but internal memory can contain unallocated gaps. When you remove an item using the delete operator or expand the length property directly, the engine creates empty slots rather than assigning the value undefined. These sparse gaps alter iteration mechanics across JavaScript arrays significantly. Built-in traversal methods such as forEach, map, and filter skip empty slots entirely, whereas modern spreading and Array.from convert those empty positions into explicit undefined values.
Inspecting an empty slot through index access produces undefined, which masks the underlying structure and causes debugging confusion. You can verify whether an index actually exists as an owned property by calling Object.hasOwn(arr, index). When memory efficiency matters, modern virtual machines switch internal representations from contiguous packed arrays to slower dictionary hash tables. This layout change degrades performance when JavaScript arrays switch from fast packed elements to dictionary mode, replacing rapid linear memory offsets with slower key lookups.
const sparseList = [10, , 30];
console.log(sparseList.length); // 3
console.log(Object.hasOwn(sparseList, 1)); // false
const mapped = sparseList.map(x => x * 2); // [20, empty, 60]
const dense = Array.from(sparseList, x => (x ?? 0) * 2); // [20, 0, 60]
const sparseList = [10, , 30];
console.log(sparseList.length); // 3
console.log(Object.hasOwn(sparseList, 1)); // false
const mapped = sparseList.map(x => x * 2); // [20, empty, 60]
const dense = Array.from(sparseList, x => (x ?? 0) * 2); // [20, 0, 60]
To prevent accidental gaps during dynamic construction, avoid setting indices beyond the current length threshold. If you must initialize a list with predetermined capacity, use Array.from({ length: size }) rather than new Array(size). The constructor form creates a collection consisting purely of empty slots, which breaks subsequent functional chains like map. The Array.from helper immediately creates a packed structure populated with real undefined entries, ensuring every transformation callback executes predictably over each assigned slot.
Serializing sparse collections through JSON.stringify introduces another surprise by converting every empty slot into null. When parsing that payload back into memory, the resulting structure is dense rather than sparse. Maintaining structural predictability requires consistent initialization patterns. Modern production systems compact sparse JavaScript arrays using non-mutating routines like toSpliced or filter passes that yield contiguous sequences without missing indices.
Performance profiling demonstrates that operations against packed collections run orders of magnitude faster than equivalent operations against holed structures. Once an engine demotes an instance to dictionary mode, restoring packed optimization requires copying elements into a freshly instantiated sequence. Establishing linting rules against manual index deletion and restricting array size mutations preserves optimal engine optimization heuristics across high-throughput data processing services.
Flattening nested structures with flat and flatMap
Handling variable depth nesting
Real-world data pipelines frequently produce deeply nested hierarchies, such as lists of orders containing line items or paginated API batches. The flat method unwraps child levels up to an optional numeric depth argument. By default, invocation strips away a single level of nesting. Passing Infinity as the argument instructs the engine to recursively flatten arbitrarily deep nestings into a single sequence. This built-in method also automatically discards empty slots, making it an efficient tool for cleaning sparse JavaScript arrays.
Evaluating flattening cost requires understanding memory allocation. Calling flat produces a completely fresh shallow copy of items located at the target depth, leaving original objects referenced by address. If you flatten large hierarchies repeatedly inside event handlers, memory usage increases rapidly due to intermediate list allocations. When you only need to process values without storing intermediate sequences, modern generators or direct iteration loops conserve memory by yielding leaf items one at a time without allocating full wrapper buffers.
Depth values can be dynamically calculated based on incoming payload metadata. When dealing with tree nodes where leaf depths vary across branches, passing an explicit numeric boundary avoids excessive traversal overhead. If an operation only needs the topmost layers merged, supplying a depth of two or three bounds memory consumption, keeping execution times predictable when processing user-submitted nested JSON documents.
Mapping and stripping invalid records
When processing records where each input item maps to zero, one, or several outputs, pairing map with flat creates unnecessary intermediary garbage. The specialized flatMap method combines both passes into a single allocation step. The projection callback runs on each entry and expects an inner sequence in return. Returning an empty sequence drops the current record, returning a single-element sequence keeps it, and returning multi-element sequences expands the output stream cleanly.
const rawEvents = [
  { id: "e1", tags: ["auth", "login"] },
  { id: "e2", tags: [] },
  { id: "e3", tags: ["billing"] }
];
const tagIndex = rawEvents.flatMap(event =>
  event.tags.map(tag => ({ tag, eventId: event.id }))
);
console.log(tagIndex.length); // 3
const rawEvents = [
{ id: "e1", tags: ["auth", "login"] },
{ id: "e2", tags: [] },
{ id: "e3", tags: ["billing"] }
];
const tagIndex = rawEvents.flatMap(event =>
event.tags.map(tag => ({ tag, eventId: event.id }))
);
console.log(tagIndex.length); // 3
This pattern proves exceptionally useful for data validation and schema normalization. Instead of executing an initial filter followed by a separate map, a single flatMap execution simultaneously removes corrupt records and reshapes valid payloads. Because flatMap only flattens to a depth of one, it prevents accidental unwrapping while maintaining throughput across large JavaScript arrays containing heterogeneous payload data.
Be mindful of the single-depth restriction when structuring recursive transformations. If an item transformation produces multidimensional nested lists that need full reduction, flatMap will not unwrap beyond the first inner boundary. In those scenarios, chain a subsequent flat call with appropriate depth, or build a recursive utility function. For the vast majority of web service integrations, the single-level unwrap provided by flatMap matches database relationship joins and API query normalization requirements perfectly.
Reference equality and lookup pitfalls in JavaScript arrays
Searching for elements requires strict attention to equality semantics. Methods such as indexOf and includes evaluate candidates using strict equality. When JavaScript arrays store primitive numbers or strings, identity comparisons evaluate predictably. However, when collections store object literals, class instances, or nested collections, matching against a newly declared literal always fails. The lookup evaluates memory addresses rather than internal properties, meaning distinct objects with identical keys evaluate as unequal under strict comparison.
To locate objects reliably, utilize predicate-based search methods such as findIndex, find, or modern findLast. These methods accept a callback that inspects specific properties, avoiding identity traps. Another edge case involves floating-point NaN values. The older indexOf method relies on standard strict equality comparisons, which report NaN === NaN as false, making NaN undetectable through index searches. Modern includes uses the SameValueZero algorithm, successfully locating NaN entries inside modern JavaScript arrays.
Consider search direction when handling chronological event logs or append-only queues. Scanning from the start using find requires traversing the entire collection when target entries reside near the end. Using findLast and findLastIndex starts the search from the final index, returning matching recent records much faster. These reverse-searching methods eliminate the need to clone and reverse chronological entries stored in large JavaScript arrays, preserving execution speed when analyzing time-stamped entries.
When performance critical paths perform repeated lookups against thousands of items, repeated scans with find or includes introduce unacceptable quadratic time complexity. Instead of scanning repeatedly, convert the collection into a keyed Map or Set indexed by unique identifiers. This provides constant-time lookups while keeping the original collection available for sequential display. Using appropriate lookup structures prevents search bottlenecks as data volumes expand across complex frontend applications.
Custom search logic should also account for negative indices when using the modern at method. Passing negative numbers allows expressive reads from the tail of a sequence without manual length subtractions. When writing validation wrappers, combining at(-1) with identity checks offers a concise mechanism for inspecting the latest state transitions in event buffers without mutating index pointers or creating ephemeral wrapper objects.
Typed arrays versus standard collections
Standard JavaScript arrays operate as flexible, dynamic lists capable of holding mixed types and resizing on demand. This flexibility incurs memory overhead because engines wrap elements in tagged pointers and allocate extra space for dynamic growth. When handling binary files, WebGL graphics, audio streams, or raw network sockets, standard collections become inefficient. TypedArray views like Uint8Array, Int32Array, and Float64Array provide direct access to contiguous, fixed-length memory buffers without pointer boxing overhead.
A TypedArray is not an extension of the standard list prototype, but rather an indexed view sitting over an underlying ArrayBuffer. Because the buffer byte size remains permanently fixed after creation, methods that change collection length, such as push, pop, and splice, do not exist on TypedArray prototypes. You can still use common transformation helpers like map, filter, and reduce, but their output will always produce another typed view constrained to the same element type.
const buffer = new ArrayBuffer(16);
const view32 = new Int32Array(buffer);
view32[0] = 42;
view32[1] = 1024;
const view8 = new Uint8Array(buffer);
console.log(view8[0]); // 42
console.log(view8.byteLength); // 16
const buffer = new ArrayBuffer(16);
const view32 = new Int32Array(buffer);
view32[0] = 42;
view32[1] = 1024;
const view8 = new Uint8Array(buffer);
console.log(view8[0]); // 42
console.log(view8.byteLength); // 16
Conversion between standard JavaScript arrays and typed views requires careful data boundary management. Passing an ordinary collection into a TypedArray constructor copies each element, truncating values that exceed the designated byte precision. For instance, assigning a floating-point number to an integer typed view silently truncates decimals, and values exceeding maximum integer ranges wrap around according to unsigned or signed modulo math. Understanding these boundaries prevents subtle data corruption during binary data ingestion.
For everyday business logic and UI state management, standard JavaScript arrays remain the superior choice due to rich utility methods, dynamic resizing, and native JSON serialization support. Reserve TypedArray implementations for high-frequency numeric streams, cryptographic operations, binary image parsing, and shared memory communication across Web Workers. Choosing the correct collection type based on memory layout requirements ensures optimal application throughput without introducing unnecessary type casting overhead.
Memory allocation and garbage collection behavior
Engines allocate memory dynamically as collections expand, but growth does not occur one element at a time. To minimize system calls, runtimes allocate memory in over-provisioned capacity chunks. When you append items beyond the current capacity boundary, the runtime allocates a substantially larger memory segment, copies existing elements over, and marks old memory for garbage collection. Continually growing large JavaScript arrays incrementally inside tight computational loops triggers repeated memory reallocations that degrade runtime performance.
Removing elements also requires deliberate memory lifecycle consideration. Truncating a collection by decreasing its length property immediately severs references to removed items, allowing the garbage collector to reclaim their memory during subsequent cycles. When clearing large JavaScript arrays, setting the length property to zero allows instant reuse of existing memory capacity while releasing contained values safely. Conversely, deleting an index with delete merely creates an empty slot, leaving adjacent references active and altering internal optimization modes.
Accidental memory retention often arises when storing complex objects inside long-lived module-level collections or global caches. When an object reference sits inside an active collection, the garbage collector treats it as reachable, preventing reclamation even if the rest of the application no longer accesses that record. If you require temporary associations without preventing garbage collection, consider using a WeakSet or WeakMap. These specialized structures hold weak references, permitting clean reclamation once primary references fall out of scope.
Another common source of memory bloat is maintaining unneeded historical states during immutability passes. When building reactive user interfaces, shallow-copying massive collections repeatedly creates numerous short-lived wrappers that stress generational garbage collection nurseries. To manage high-frequency state updates efficiently, partition massive JavaScript arrays into smaller logical chunks or update localized subsets. Keeping collection sizes bounded minimizes memory pressure and avoids noticeable application frame drops.
Monitoring heap consumption in modern developer tools reveals hidden retained sizes caused by lingering closures. When callbacks passed to transformation methods capture outer scope variables, those captured references remain tethered to the lifecycle of the collection. Disconnecting event handlers and nullifying obsolete references after batch computations allows the garbage collector to reclaim memory before subsequent application tasks begin.
Sorting stability and custom comparator gotchas
Sorting elements remains one of the most error-prone operations when working with JavaScript arrays. Calling sort or modern toSorted without an explicit comparator function does not sort numbers numerically. Instead, the engine converts every element into a string and compares their UTF-16 code unit values alphabetically. As a consequence of this design, the number 100 sorts before the number 25, producing unexpected sequences in financial and numerical applications.
Providing a custom comparator resolves numerical order, but subtraction-based shortcuts introduce risks. Writing (a, b) => a - b works well for standard integers, but encounters severe errors when handling floating-point values that overflow or collections containing NaN. If either operand evaluates to NaN, the subtraction yields NaN, breaking comparator symmetry. Modern ECMAScript requires sorting algorithms to remain stable, preserving relative original positions in processed JavaScript arrays.
When sorting international strings, avoid manual greater-than or less-than comparisons, which ignore regional accent conventions and local sorting alphabets. Use String.prototype.localeCompare inside the comparator callback. This standard internationalization helper handles accented characters, case sensitivity, and language-specific collation orders accurately. Furthermore, you can supply language tags and sensitivity options to customize collation rules across multinational application interfaces, ensuring reliable presentation order across user demographics.
For complex multi-criteria sorting, compose comparator functions that evaluate fallback conditions sequentially. If primary attributes compare equally, the comparator immediately inspects secondary fields. Utilizing non-mutating toSorted ensures your source data remains unaltered, preserving referential integrity for component render cycles. Adhering to strict comparator contracts guarantees deterministic ordering across all modern browser engines whenever sorting complex JavaScript arrays.
Performance considerations also dictate keeping comparator callbacks lightweight. Because sorting algorithms invoke the comparator multiple times per element during partitioning, performing expensive object lookups, string formatting, or cryptographic hashing inside the callback degrades execution speed. When sorting by computed keys, map elements to lightweight tuple pairs containing the precomputed key and original item, perform the sort, and extract the sorted items in a single linear pass.
Frequently asked questions
What is the difference between map and forEach?
map returns a new array of transformed values so it can be chained. forEach returns undefined and is used when you want to run a side effect for each item.
How do I copy an array without changing the original?
Use the spread operator, as in […arr], or the non-mutating methods toSorted, toReversed and toSpliced, which return a new array instead of modifying the original.
What does reduce do in JavaScript?
It walks an array and combines every item into one value using a callback and a starting accumulator, such as summing an array of numbers.
How do I access a property with a dynamic name?
Use bracket notation with a variable, such as obj[key]. Dot notation only works with a literal property name known when you write the code.
What is object destructuring?
It pulls properties out of an object into local variables in one line, with optional defaults and renaming, for example const name, role = guest from user.
Last updated on · Written by Dinesh Kumar R
