


Five studies ask the same question and disagree. Two find an effect, two find nothing, one finds the opposite. A narrative review resolves this by counting votes, which weights a 40-person pilot the same as a 40,000-person trial. A meta-analysis instead pools the effect estimates, weighting each study by its precision.
Done well, that produces a more precise answer than any single study. Done badly, it produces a confident-looking number from studies that were never comparable — and the confident-looking number travels further than the caveat underneath it.
Table of Contents
What a meta-analysis adds that a review cannot
Three things, in order of importance. It increases precision by combining information. It makes heterogeneity visible and quantifiable rather than leaving it as disagreement in prose. And it forces the assumptions into the open, because pooling requires stating explicitly what effect you are estimating and which studies measure it.
What it cannot do is manufacture evidence that does not exist. If all included studies are biased in the same direction, pooling gives you a very precise biased estimate — the classic garbage-in, confident-out failure.
The effect size is the unit of analysis
The single most common beginner error is pooling p-values. A p-value conflates effect size with sample size, so averaging them is meaningless. Meta-analysis pools a standardised measure of effect, extracted from each study.
| Outcome type | Effect measure | Notes |
|---|---|---|
| Continuous, same scale | Mean difference | Preferred when units are identical |
| Continuous, different scales | Standardised mean difference (Hedges g) | Comparable but unitless; small-sample correction matters |
| Binary, common outcome | Risk ratio or odds ratio | Odds ratios exaggerate when events are common |
| Binary, rare outcome | Odds ratio or risk difference | Zero cells need continuity correction |
| Time to event | Hazard ratio | Requires extracting log HR and its SE |
| Correlation | Fisher z transformation | Back-transform for presentation |
Every measure needs its variance, not just its point estimate. Software needs the standard error or the confidence interval, and extracting that correctly from each paper is where most of the real labour lives — a meta-analysis is a data-extraction project before it is a statistical one.
# R: the meta package covers most designs
library(meta)

# Continuous outcome, standardised mean difference
m <- metacont(n.e = n_e, mean.e = mean_e, sd.e = sd_e,
              n.c = n_c, mean.c = mean_c, sd.c = sd_c,
              studlab = study, data = dat,
              sm = "SMD", method.smd = "Hedges",
              common = FALSE, random = TRUE)
summary(m)
Fixed versus random effects
These two models answer different questions, and choosing between them is an assumption about the world rather than a technical preference.
| Fixed (common) effect | Random effects | |
|---|---|---|
| Assumption | One true effect; studies differ only by sampling error | A distribution of true effects across settings |
| Question | What is the effect in these studies? | What is the average effect in the population of studies? |
| Weighting | Precision only, so large studies dominate | Precision plus between-study variance |
| When heterogeneity is high | Overconfident, too narrow CI | Wider CI, more honest |
| Typical default | Only when studies are near-identical | Most real syntheses |
The random-effects model never gives a narrower confidence interval than the fixed-effect model, and that widening is the price of acknowledging that studies are not measuring one identical quantity. With very few studies, the between-study variance is poorly estimated, which is why some methodologists recommend a Hartung-Knapp adjustment or a Bayesian approach in small meta-analyses.
# Explicitly compare both, and report which you rely on
m_fixed  <- update(m, common = TRUE,  random = FALSE)
m_random <- update(m, common = FALSE, random = TRUE)
m_random$TE.random
m_random$I2
Heterogeneity: I² and what it does not mean
I² is the proportion of total variability across studies attributable to real differences rather than chance. It is reported everywhere and misread constantly: I² is not the proportion of studies that disagree, and it is not a measure of how much the effect varies.
| Statistic | What it is | Reading |
|---|---|---|
| Q | Test statistic for heterogeneity | Low power with few studies; significance is not the point |
| I² | Share of variability beyond sampling error | 25/50/75% are loose conventions, not thresholds |
| tau² | Estimated variance of true effects | The quantity that actually widens the interval |
| Prediction interval | Where a future study’s effect would plausibly fall | Usually far wider than the CI — report it |
The prediction interval is the underused one. A pooled effect with a 95% CI of 0.75 to 0.85 and a 95% prediction interval of 0.45 to 1.40 tells a genuinely different story from the CI alone: the average effect is precise, but a new setting could plausibly see no benefit at all.
Also note that I² rises mechanically as studies get larger, because sampling error shrinks while true differences do not. Comparing I² across meta-analyses with very different study sizes is therefore misleading.
Reading a forest plot
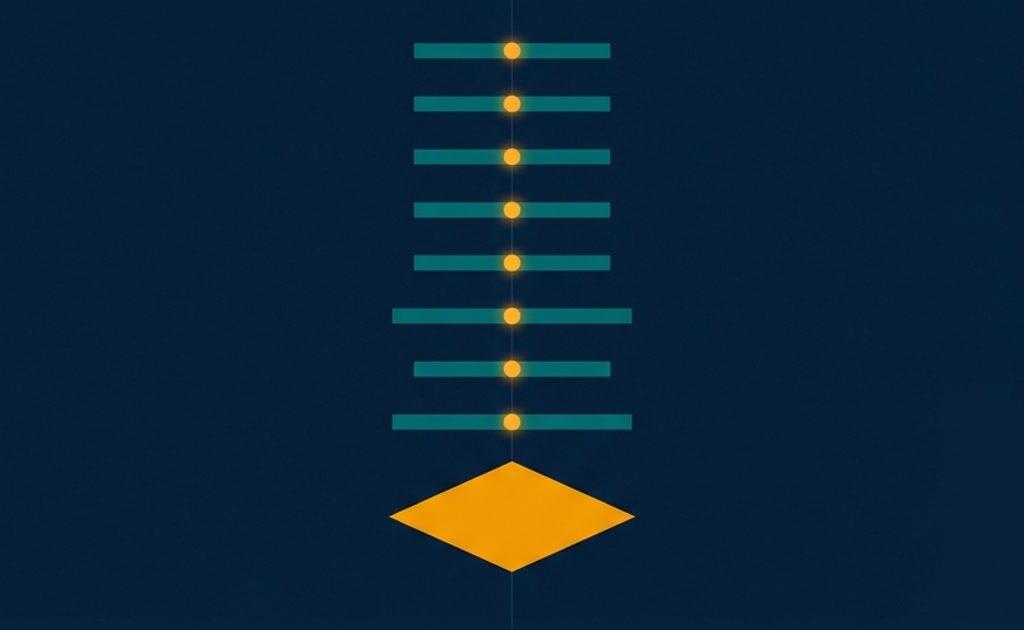
Each row is a study: a point estimate and a confidence interval, usually scaled so the box area reflects weight. The diamond at the bottom is the pooled estimate — its width is the CI. The vertical line is no effect.
- A CI that crosses the vertical line means that study alone did not reach significance; it does not mean the study found nothing.
- Unequal box sizes show how much each study drives the pooled result. If one dominates and it is the weakest study, the result is fragile.
- The diamond sitting to one side of most study estimates suggests the model is doing something other than averaging what you see.
- A wide diamond partly overlapping no effect, with a narrow-looking individual study, usually means high heterogeneity.
forest(m, sortvar = TE,
       prediction = TRUE,
       print.tau2 = TRUE, print.I2 = TRUE,
       label.left = "Favours control", label.right = "Favours treatment")
Publication bias
Studies with null or negative results are less likely to be published, so a meta-analysis can inherit a literature that is systematically positive. Two diagnostics help, neither proves anything.
The funnel plot puts effect size against precision; in the absence of bias it should look like a symmetric inverted funnel. Asymmetry suggests small studies with large effects are over-represented. Egger’s test formalises that, but it has low power with fewer than ten studies and can be triggered by genuine heterogeneity rather than bias.
funnel(m, studlab = TRUE)
metabias(m, method.bias = "Egger")
If asymmetry is present, trim-and-fill estimates how many studies might be missing and what the adjusted effect would be. Treat the adjusted value as a sensitivity analysis, not a corrected truth — it assumes a specific mechanism for the missing studies.
What to report
Report the search strategy and inclusion criteria, the effect measure with its rationale, the model (fixed or random) and why, tau-squared and I², the pooled estimate with CI, the prediction interval, a forest plot with weights, a heterogeneity discussion, and a bias assessment. If you changed the analysis after seeing results, say so — that is the meta-analytic version of p-hacking.
Pooling is a judgement about comparability as much as a calculation. If you want to build that judgement on a firmer foundation, Ampersand Academy covers the design and appraisal side of evidence synthesis.
Practice
- Re-run a published meta-analysis with a fixed-effect model and compare the CI width with the random-effects result.
- Report the prediction interval and state in one sentence what it implies for a new setting.
- Produce a funnel plot for a synthesis with fewer than ten studies and explain why Egger’s test is unreliable there.
- Remove the largest study and describe how the pooled estimate and I² change.
Related tutorials
- Effect Size in Statistics: Cohen d, r and Eta-Squared — the effect sizes that actually get pooled
- Confidence Intervals Explained: Read Them Like a Reviewer — the intervals every row of a forest plot is built from
- Repeated Measures Are Not Independent: When to Use Mixed Models — random effects, the same idea applied to clustered data
Can I pool p-values instead of effect sizes?
You can combine p-values mathematically, but the result tells you only whether some effect exists somewhere, not how large it is. Meta-analysis pools effect estimates with their variances so the output is an interpretable magnitude with a confidence interval.
Fixed or random effects — which should I use?
Random effects for most real syntheses, because studies differ in populations, doses and settings, so a single common effect is unrealistic. Fixed effect is defensible when studies are genuinely near-identical, and reporting both with the reasons is good practice.
What does an I² of 70% mean?
About 70% of the observed variability between study estimates is attributable to real differences rather than sampling error. It does not say the studies disagree in direction, and it does not measure the size of the effect variation — tau-squared and the prediction interval do that.
How many studies do I need for a meta-analysis?
Two is the mathematical minimum, but random-effects variance and bias tests are unreliable with fewer than about five to ten. With very few studies, use a Hartung-Knapp adjustment, avoid Egger’s test, and interpret heterogeneity qualitatively.
Is a non-significant pooled effect evidence of no effect?
No. A wide confidence interval means the data are compatible with benefit and harm. Absence of evidence is not evidence of absence, and the prediction interval usually makes that clearer than the pooled CI.
What is a prediction interval and why report it?
It estimates where the true effect of a future study in a new setting would plausibly fall, accounting for both sampling error and between-study variance. It is usually much wider than the confidence interval and is far more useful for someone deciding whether to apply the result.
How do I handle studies with zero events?
Zero cells make odds ratios and risk ratios undefined. Options are a continuity correction, the Mantel-Haenszel method without correction, or a beta-binomial model. Check that your choice does not distort the pooled estimate, especially when zero events are common.